


Model availability, context length, and final prices may vary by model. Use the prices displayed in the console as the source of truth before starting production traffic.
Supported Model Types
AI Gateway supports multiple categories of models for common AI workloads.Pricing
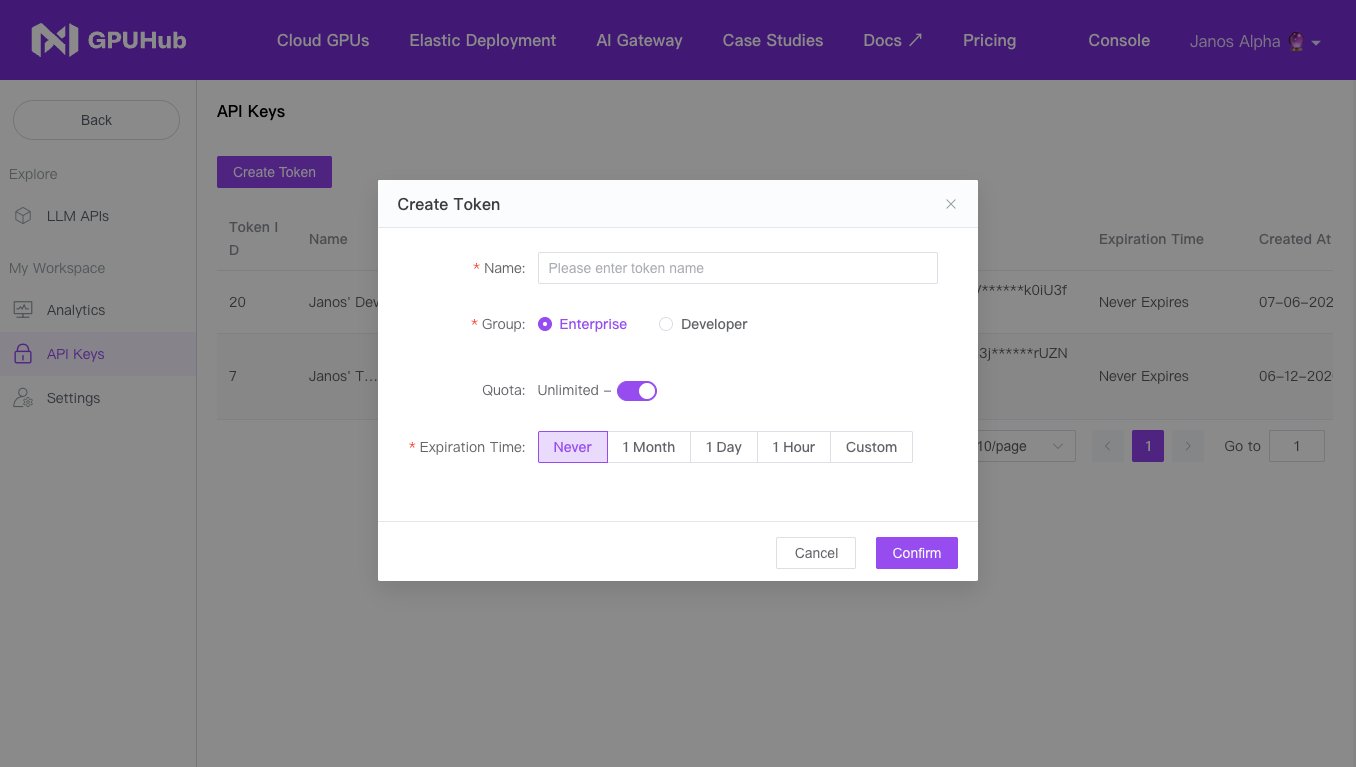
AI Gateway provides two service plans: Enterprise for production workloads and Developer for individual or experimental use. Model prices are listed in USD. Always use the unit prices displayed in the console as the source of truth.Enterprise
Production-grade API access for enterprise workloads, with priority capacity, higher service stability, and dedicated support. Suitable for commercial applications, high-volume usage, and business-critical AI services.
Developer
Affordable API access for individual developers, testing, and non-critical workloads. Powered by shared capacity, with best-effort availability and performance that may vary depending on resource availability.
The prices below are placeholders used to illustrate each billing formula. They do not represent actual model prices.
Language Models
General language models are billed by token usage.
Billing formula:
Tiered Context Pricing
Some language models select a pricing tier based on the total number of input tokens in a request. After the tier is selected, its input and output prices apply to the entire request.
Standard-context formula:
Claude-Series Prompt Caching
Claude-series models may include prompt caching charges in addition to normal input and output token charges.
Billing formula:
Usage Notes
- Check the console for the latest model list, supported parameters, context limits, and real-time prices.
- For language models, estimate cost from both input and output tokens. Long prompts, retrieved documents, and tool results can increase input token usage.
- For tiered-context models, the input token count determines which price pair applies to the entire request.
- For cached prompts, cache writes and cache reads may appear as separate billable usage types.
- Use rate limits and budget controls when integrating AI Gateway into production applications.